

Context
Most AI products send every request to one model, because picking a model per request without losing quality is hard. The cheapest model that does the job changes from one request to the next, and only your own requests show which one it is. Off-the-shelf routers rely on classifiers trained on generic data, and teams compare models on public benchmarks, which measure someone else’s tasks. Neither tells you how a model will perform on your requests, so switching to a model that looks better on paper can still change how your agent behaves.How Benchmark-Driven Routing works
Weflayr routes on how models perform on your own requests:- It benchmarks candidate models on your own past calls, against the model you use today.
- It routes each new call based on how each candidate performed on similar calls, following your cost and quality objective.
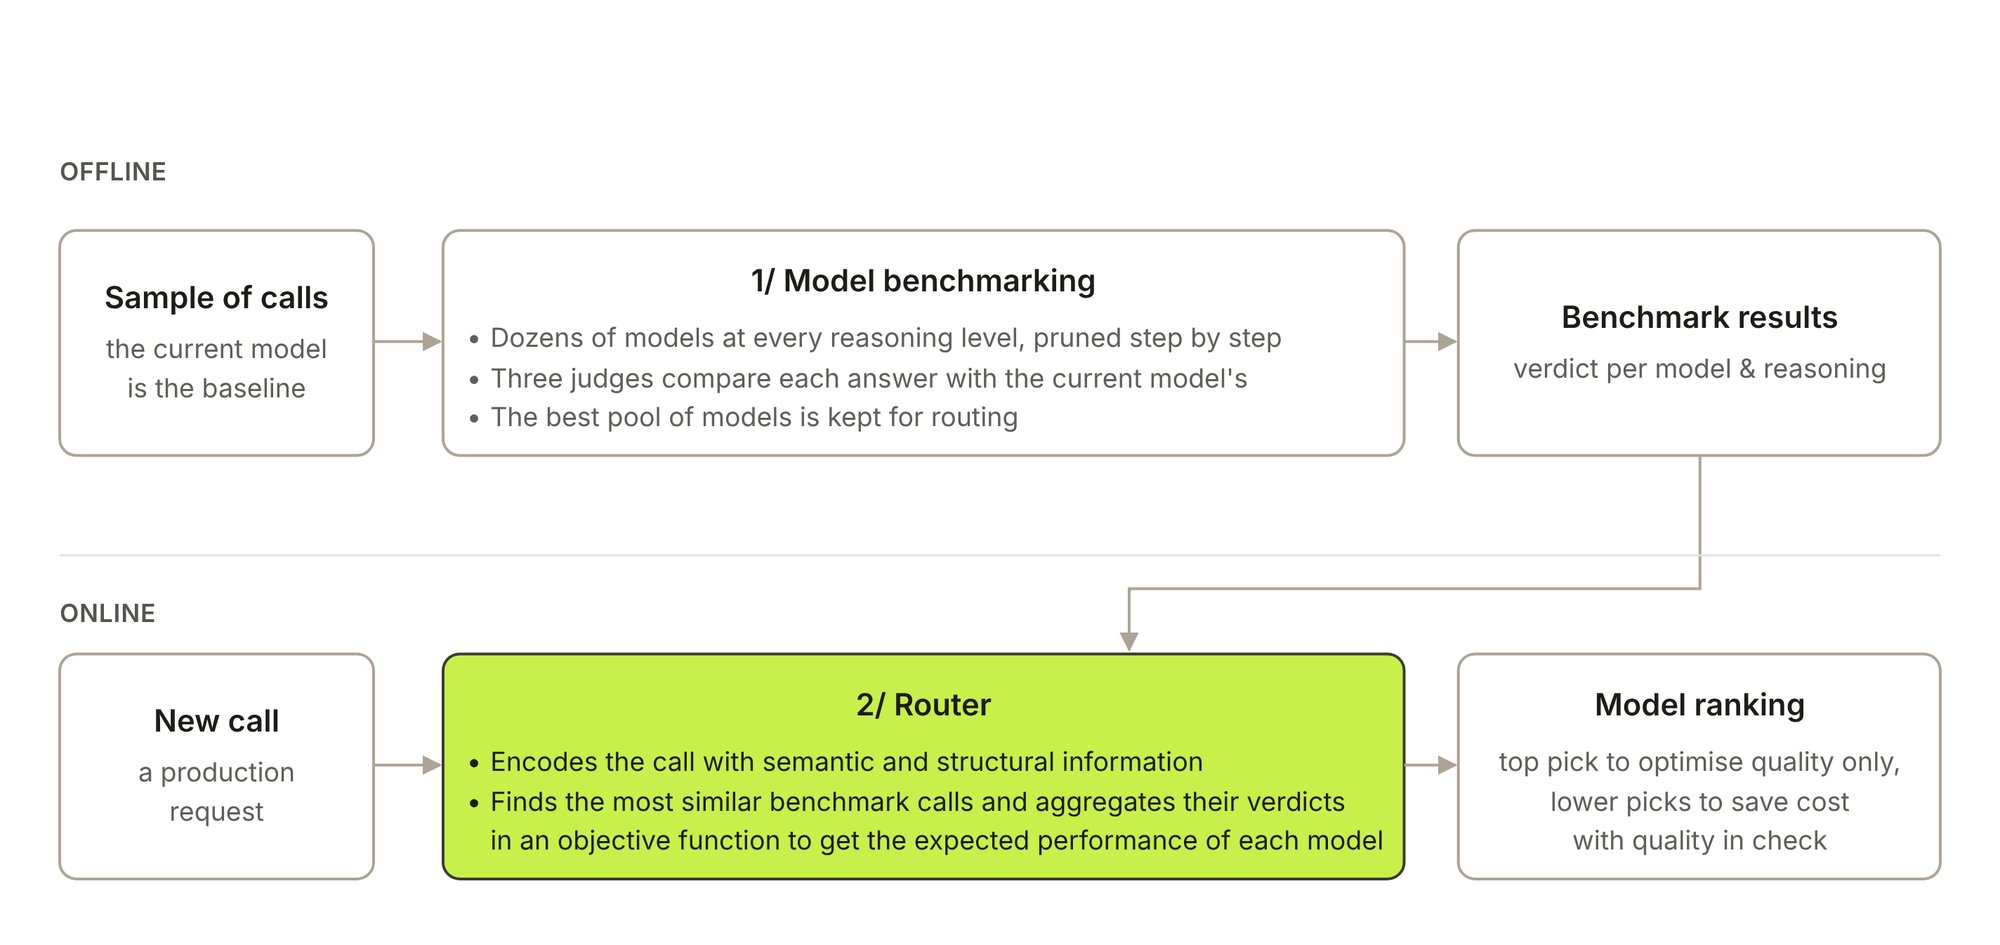

Benchmarking
How candidate models are replayed on your calls and judged against your current model.

Routing
How the router picks the model for each new call.
Results
On 1,177 test calls over 11 use cases, the Best quality objective beats Claude Opus 5.5 on quality (+20 points) at 71% lower cost, and Same quality beats it slightly (+5 points) at 89% lower cost, ahead of OpenRouter’s Auto Router and of the published routers of LLMRouterBench.
How Weflayr's Benchmark-Driven Routing outperforms leading LLM routers on quality and cost
The full setup, datasets and results.