A benchmark replays the calls of one of your call names on candidate models, and evaluators judge each answer against your current model’s. From those verdicts, Weflayr recommends a mix of models for each optimization objective (same quality at a lower cost, better quality at the same cost, or the best quality) and checks it on calls kept aside. A routing strategy made from it then sends each new call to the model of the mix that did best on similar calls. More info on how it works. Different ways to create a benchmark:
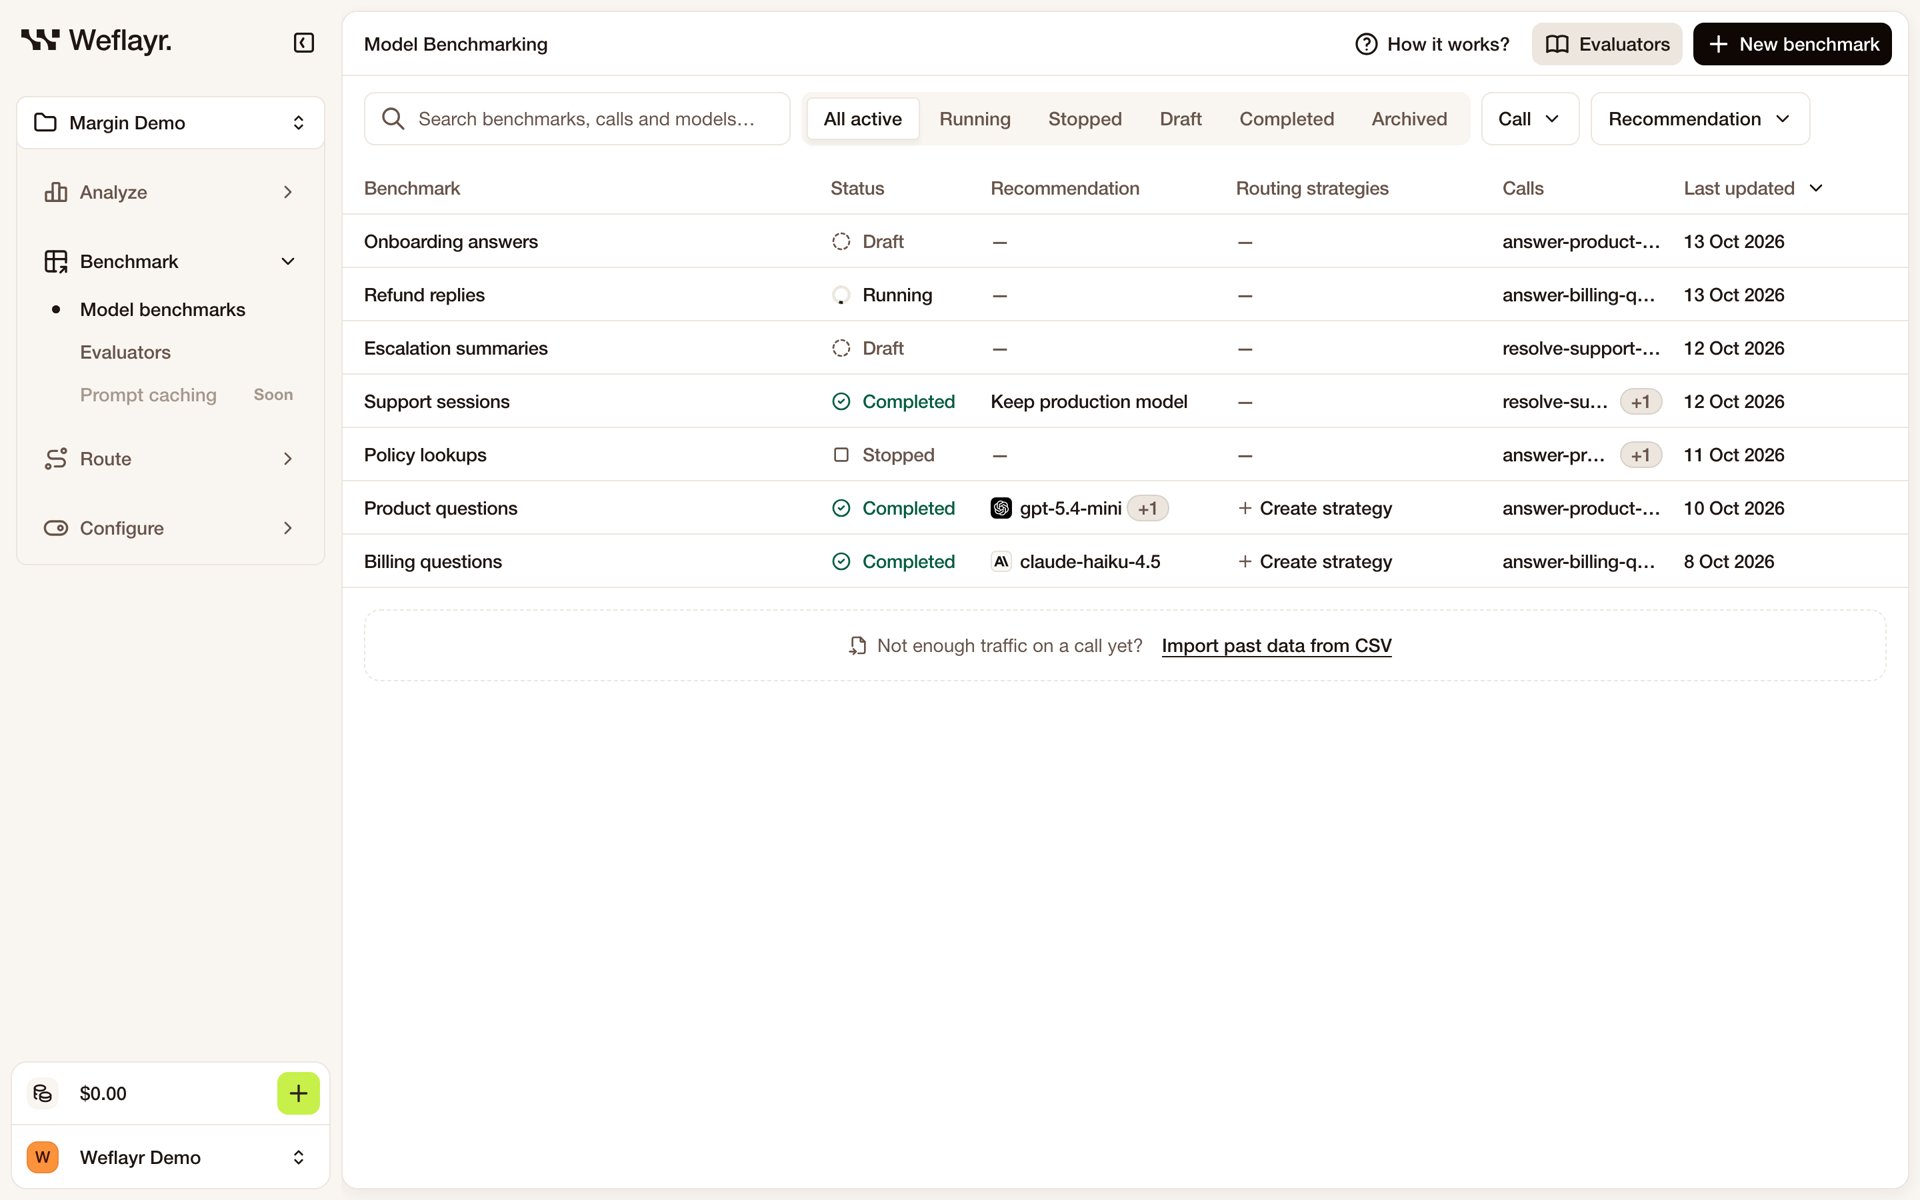
Model benchmarking page listing benchmarks with their status, recommendation and routing strategies
A running or stopped benchmark opens on the step its run is in, the models it compares and what it has spent. Pause benchmark stops a running one and gives back the credit it reserved and did not spend, and Resume continues it.

Import past calls

Benchmark calls you logged elsewhere, from a CSV or via API.

Create a benchmark

Pick a call, the models to try and how to judge them.

Benchmark report

Read the results and turn them into a routing strategy.