Improvements it proposes
Weflayr looks at each feature’s real calls, measures how much of that achievable caching you already capture, and proposes two kinds of improvements to capture the rest:- Config changes: finds the best the caching settings based your AI calls and on each provider’s own caching rules (retention, explicit vs implicit caching, minimum cacheable length, breakpoints and so on).
- Prompt-structure changes: reorders the prompts when it makes sense so more of it can be cached.
Details on prompts
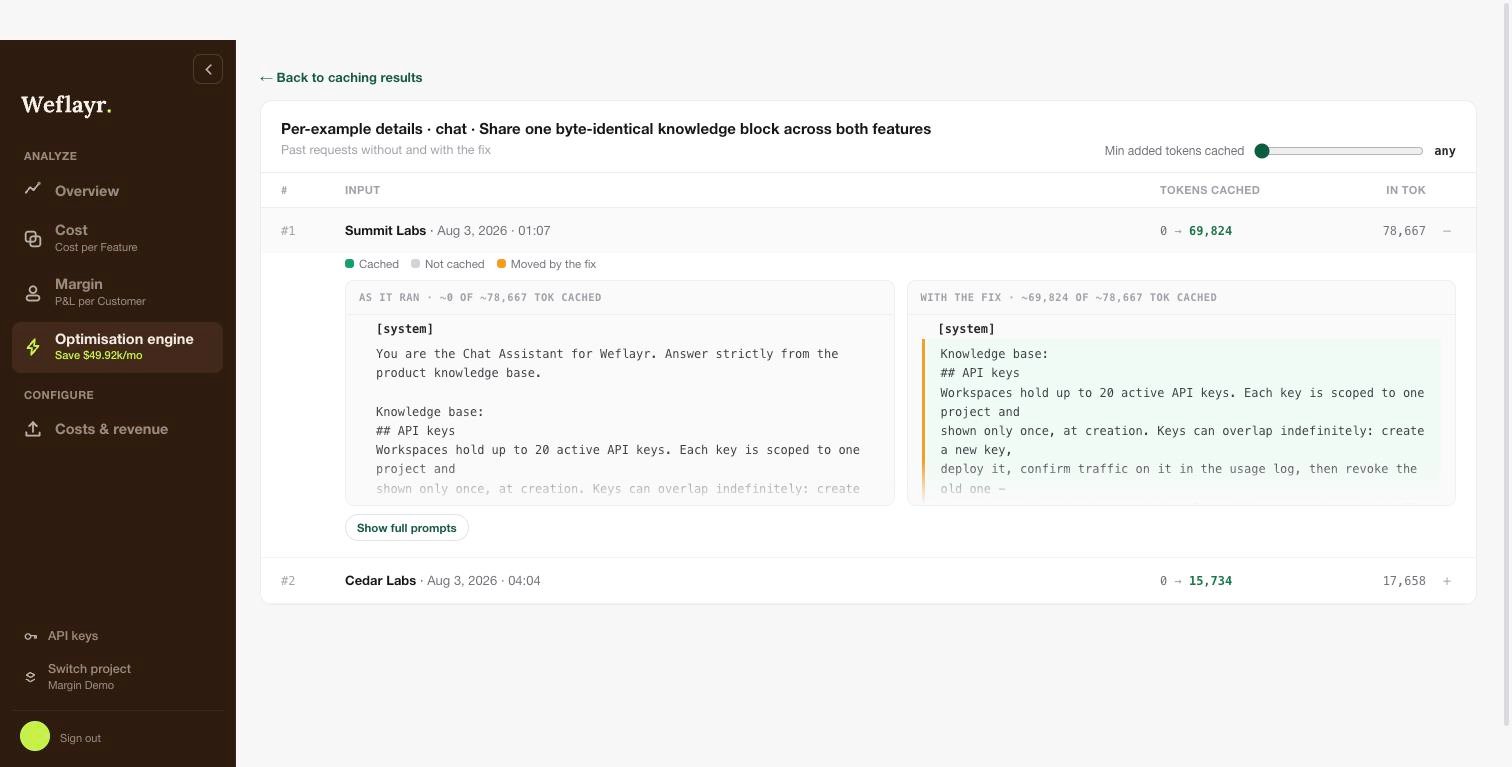
View details on prompts on a finding shows the real calls it applies to, each as it ran versus with the fix, highlighting the tokens that would move into cache.